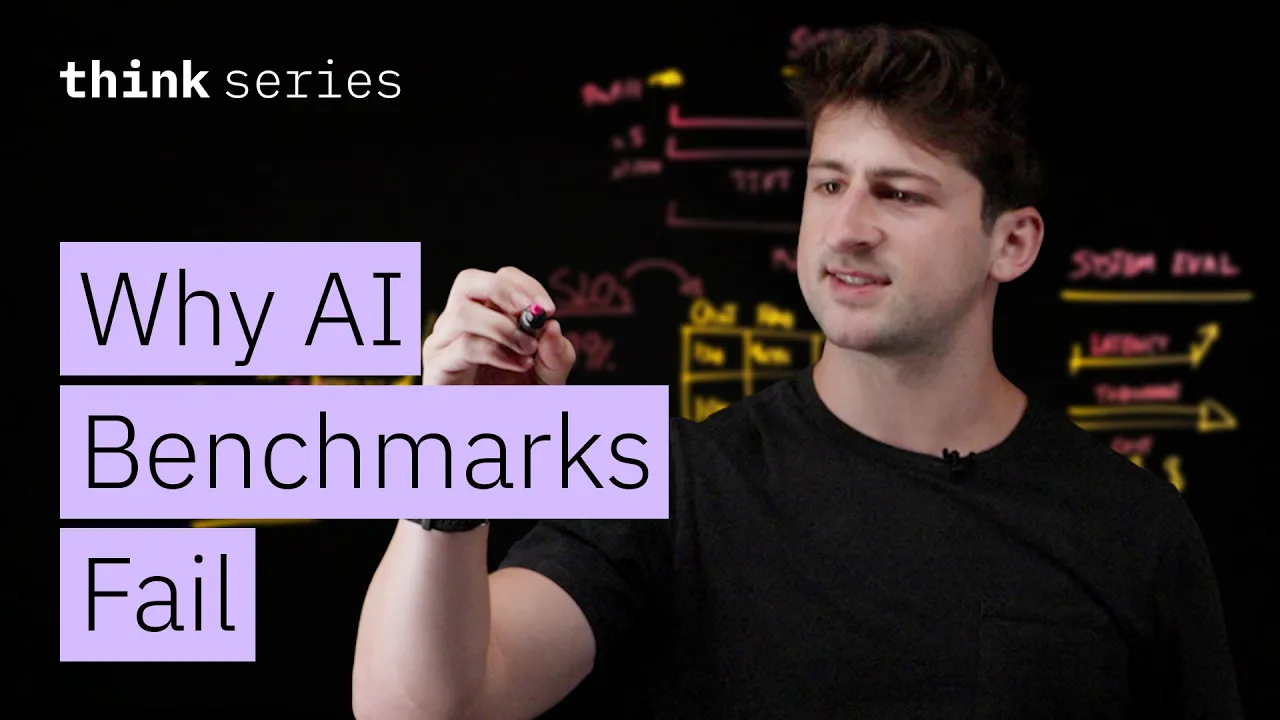
LLM & AI Agent Benchmarks vs Reality: Why AI Applications Break
202616 분
Learn more about LLM Benchmarks here → https://ibm.biz/~e64ktvs52
Your AI model scored high, but does it actually work? Cedric Clyburn explains why LLM benchmarks don’t reflect real-world performance in AI applications and agents. Learn how to evaluate accuracy, latency, and cost to build reliable AI systems at scale.
AI news moves fast. Sign up for a monthly newsletter for AI updates from IBM → https://ibm.biz/~8qaatdRba
AI was used in the creation of the transcript and metadata for this video.
#llm #aievaluation #aiengineering #aiagents #machinelearning
You cannot order from yourself. Manage this offer in your panel.
This creator has not set their rates yet. Send a request and we will pass it on — the price is agreed before anything is charged.
Monthly participation
per month
A recurring seat in my content. Subscribers enter a queue — or a random draw when there are more subscribers than slots — and appear in the video itself, in the credits, or in the description.